10. The TTS pipeline and the two meanings of streaming
What you will learn
- The three stages of a text-to-speech (TTS) system, what passes between them, and how many frames per second each stage produces.
- How TTS models evolved, one line per family, and which families can produce audio before they have read all the text.
- The two meanings of "streaming" in TTS, output streaming and input streaming, and why a voice agent needs both.
- Why models that decide the length of the whole utterance first resist streaming, shown in code.
Before you start
- Chapters: 1 and 2 (samples, mel spectrograms, the phase a spectrogram drops), 3 (time to first audio).
- Tools: none for reading. Try it uses the
ssh-tts-cpuenvironment fromcode/tts/README.md.
Three stages
A TTS system turns text into a waveform in three stages.
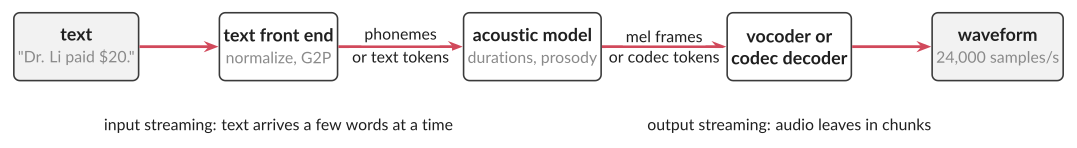
The text front end turns written text into something that says how to pronounce it. "Dr. Li paid $20." must become "doctor Li paid twenty dollars" (text normalization, TN) and then a sequence of phonemes (grapheme-to-phoneme conversion, G2P). Many modern models skip explicit phonemes and read text tokens directly, which moves the same problem inside the model.
The acoustic model decides how long each sound lasts and how the voice rises and falls (prosody), and produces an intermediate representation: either a mel spectrogram or a sequence of codec tokens (chapter 11).
The vocoder turns that representation into samples. A mel spectrogram has thrown away the phase (chapter 2), so a vocoder must invent a consistent one; a codec decoder reconstructs audio from its own tokens. Chapter 13 is about this stage.
Each stage runs at its own clock. The exemplars of this book, from their configurations:
| System | Output rate | Hop | Frames per second | Bins | Source |
|---|---|---|---|---|---|
| Tacotron 2 | 24 kHz (vocoder) | 12.5 ms | 80 | 80 | arXiv:1712.05884, Secs. 2.1 and 2.3 |
| HiFi-GAN V1, Matcha-TTS | 22,050 Hz | 256 samples, 11.61 ms | 86.13 | 80 | hifi-gan/config_v1.json; Matcha-TTS/configs/data/ljspeech.yaml |
| Vocos, BigVGAN-v2 24 kHz, F5-TTS | 24,000 Hz | 256 samples, 10.67 ms | 93.75 | 100 | vocos/configs/vocos.yaml; BigVGAN config; F5-TTS utils_infer.py |
| CosyVoice 2 and 3 | 24,000 Hz | 480 samples, 20 ms | 50 | 80 | examples/libritts/cosyvoice2/conf/cosyvoice2.yaml |
| Kokoro-82M | 24,000 Hz | 300 samples, 12.5 ms | 80 (durations at 40) | 80 | kokoro/pipeline.py, config.json |
Almost every TTS model here writes 24 kHz audio, while the recognizers of chapters 1-9 read 16 kHz. Chapter 1's resampling happens between them.
The families in one line each
- Tacotron 2 (2017): an autoregressive attention model predicts mel frames one by one from characters, and a WaveNet vocoder renders them (arXiv:1712.05884).
- FastSpeech 2 (2020): non-autoregressive; all frames are predicted at once from phonemes, with explicit durations, "obtained by forced alignment" in training and from a duration predictor at inference (arXiv:2006.04558, Secs. 2.2-2.3).
- VITS (2021): one end-to-end model from phonemes to waveform, with a flow-based stochastic duration predictor (arXiv:2106.06103). StyleTTS 2 (arXiv:2306.07691), the base of the CPU track's Kokoro, is also non-autoregressive, with an explicit duration predictor (see Kokoro below).
- Codec language models (2023 on): a language model writes discrete audio tokens one step at a time, like text, and a codec decoder turns them into sound. VALL-E was the first widely known one (arXiv:2301.02111); Qwen3-TTS, on the GPU track, is a recent one.
- Flow matching (2023 on): a model transforms noise into a mel spectrogram in a few steps, often conditioned on tokens from a language model. F5-TTS is pure flow matching; CosyVoice 2 and 3 chain a token language model and a flow-matching model.
The order matters for streaming. Autoregressive models produce output in time order, so they can hand over the first frames while still working on the rest. Models that predict all frames at once cannot, without extra machinery.
Two meanings of streaming
"Streaming TTS" is used for two different things, and many systems do only one.
Output streaming means audio leaves the system in chunks while the rest is still being generated. The listener hears the first syllable before the last is synthesized. This is what reduces time to first audio (TTFA, chapter 3) for a text that is known in full.
Input streaming means the system starts synthesizing before it has received all the text. CosyVoice 2 uses the word "streaming" in exactly this sense: "Here, 'streaming mode' means the input text is received in a continuous flow rather than being known as a complete sentence in advance" (arXiv:2412.10117, Sec. 2.3).
A voice agent needs both, because its text comes from a language model that writes it a few tokens at a time (chapter 18). Waiting for the language model to finish and then synthesizing the whole reply adds the entire generation time to the user's wait; SpeakStream's authors say this kind of whole-utterance TTS behind a streaming LLM would "introduce unacceptable delays" (arXiv:2505.19206, abstract). A system that does both is often called bi-streaming or dual-streaming.
Input streaming has costs of its own. A model that has not yet seen the end of the sentence must choose the prosody of its beginning without it. One 2026 paper names the two failure modes: "unnatural prosody due to missing lookahead", and long-form collapse "due to unbounded context". It reports long-text WER falling from 71.0% to 4.8% with its prosodic-boundary-aware method (arXiv:2603.06444, abstract). Text normalization also becomes harder: "Dr." at the end of a fragment may be "doctor" or "drive", and the number in "$20" may still be growing. StreamTN's authors note that asking the dialogue LLM itself to normalize brings "high first-token latency due to non-streaming processing, hallucination risks" (arXiv:2609.24267, abstract).
The code of real systems shows how unfinished this is. CosyVoice's front end normalizes text with
ttsfrd or wetext and splits it into segments of about 60 to 80 tokens, each synthesized separately;
but when the text arrives as a generator, it prints "get tts_text generator, will skip text_normalize!"
and skips normalization entirely
(cosyvoice/cli/frontend.py, lines 127-160).
Text streamed in from an LLM gets no normalization on that path.
Why models that plan the whole utterance resist streaming
FastSpeech-style models decide every phoneme's duration before they produce any frame. The total length of the output is fixed from the whole input. Flow-matching models such as F5-TTS fix the duration from the text length too, and then refine all frames together.
You can see the consequence in F5-TTS's streaming server. It computes the duration from the text length,
duration = ref_audio_len + int(ref_audio_len / ref_text_len * gen_text_len / local_speed), synthesizes
the whole text batch, and only then cuts the finished waveform into 2,048-sample pieces:
for j in range(0, len(generated_wave), chunk_size): yield generated_wave[j : j + chunk_size], target_sample_rate
(utils_infer.py, lines 496-538).
The audio streams out, but the first piece waits for the whole first text batch (the server splits long text
into batches and synthesizes them in order). That is output streaming of the
transport, not of the generation.
Research works around this. SyncSpeech describes non-autoregressive models as experiencing "high latency due to their unordered temporal nature" and reports that, fed by a streaming LLM, it shortens the time to first audio by factors of 3.7 for English and 5.8 for Mandarin (arXiv:2502.11094, abstract). The common practical answer is the one CosyVoice 2 takes and chapter 12 explains: let an autoregressive model emit tokens in time order, and run the non-autoregressive part on short chunks of them.
The CPU track's model: Kokoro
Kokoro-82M, the CPU track's synthesizer, is a StyleTTS 2 model with an iSTFTNet vocoder (a vocoder that predicts a short spectrum per frame and finishes with an inverse STFT, chapter 13), 82M parameters, Apache 2.0 weights; v1.0 has 8 languages and 54 voices (hexgrad/Kokoro-82M model card). It predicts all durations of its input at once, so it cannot stream within one call. Its Python pipeline streams by segments instead, and the default segment is larger than most people assume:
- the text is split on newlines (
split_pattern: Optional[str] = r'\n+'), so the default segment is a paragraph, not a sentence (kokoro/pipeline.py, line 366); - G2P runs on the whole segment, and an English segment is cut only when its phonemes would exceed 510,
the model's context (
if next_pcount > 510, lines 205-231), preferably at a sentence end; - each piece is synthesized whole and then yielded.
So the first audio of a paragraph waits for G2P of the whole paragraph and synthesis of up to 510 phonemes. To get sentence-level streaming, the caller must split the text into sentences first. Chapter 12 measures what that changes.
Kokoro's G2P is the misaki library for English, Japanese and Chinese, with espeak-ng as the fallback for out-of-vocabulary English words and as the G2P for the other languages (pipeline.py, lines 116-144). misaki is Apache 2.0; espeak-ng is GPL-3.0, so a deployment that uses the fallback ships a GPL component.
Common misconceptions
"Streaming TTS" means one thing. Output streaming and input streaming are different properties. Ask which one a system has before comparing TTFA numbers.
"A server that sends audio in chunks is streaming synthesis." F5-TTS's server sends chunks of a waveform whose first text batch was synthesized whole. The first chunk waits for that whole batch.
"The text front end is a solved preprocessing step." With text arriving from an LLM a few tokens at a time, normalization must decide on unfinished fragments, and at least one major open-source system skips it on that path.
Try it
CPU track
- In the
ssh-tts-cpuenvironment, synthesize a three-paragraph text with Kokoro'sKPipelinetwice: once as written, once with every sentence on its own line. Time the first yielded chunk in each case (code/tts/ch12_kokoro_cpu/kokoro_stream.pydoes this systematically; its results are in chapter 12). - Feed Kokoro "Dr. Li paid $20 on 3/4." and listen to how misaki reads the abbreviation, the amount and the date.
GPU track
Read the streaming path of the GPU track's server (vLLM-Omni serving Qwen3-TTS, code/tts/gpu/) and find
out whether it streams input, output or both. Chapter 12 measures it.
English and Mandarin
Mandarin text needs its own front end: misaki's Chinese G2P imports jieba for word segmentation,
pypinyin for pronunciation and cn2an for numerals (misaki/zh.py, lines 2-5). Feed Kokoro's Mandarin
voice "2026年10月29日" and listen to how the date is read.
Key terms
- text normalization (TN): rewriting numbers, abbreviations and symbols as words.
- grapheme-to-phoneme (G2P): converting written words into phonemes.
- acoustic model: predicts durations, prosody and a mel spectrogram or codec tokens.
- vocoder: turns a mel spectrogram into a waveform; a codec decoder does the same from codec tokens.
- autoregressive / non-autoregressive: producing output one step at a time in order, or all at once.
- output streaming: audio leaves in chunks before generation is complete.
- input streaming: synthesis starts before all the text has arrived.
- bi-streaming: both at once.
Sources
- Shen et al., "Natural TTS Synthesis by Conditioning WaveNet on Mel Spectrogram Predictions" (Tacotron 2), arXiv:1712.05884.
- Ren et al., "FastSpeech 2: Fast and High-Quality End-to-End Text to Speech", arXiv:2006.04558.
- Kim et al., "Conditional Variational Autoencoder with Adversarial Learning for End-to-End Text-to-Speech" (VITS), arXiv:2106.06103.
- Wang et al., "Neural Codec Language Models are Zero-Shot Text to Speech Synthesizers" (VALL-E), arXiv:2301.02111.
- Du et al., "CosyVoice 2: Scalable Streaming Speech Synthesis with Large Language Models", arXiv:2412.10117; FunAudioLLM/CosyVoice (commit 074ca6d),
cosyvoice/cli/frontend.py. - Bai et al., "SpeakStream: Streaming Text-to-Speech with Interleaved Data", arXiv:2505.19206.
- Sheng et al., "SyncSpeech: Efficient and Low-Latency Text-to-Speech based on Temporal Masked Transformer", arXiv:2502.11094.
- Liu et al., "Prosodic Boundary-Aware Streaming Generation for LLM-Based TTS with Streaming Text Input", arXiv:2603.06444.
- Li et al., "StreamTN: A Low-Latency Streaming Chinese Text Normalization Model for Streaming TTS in Dialogue Systems", arXiv:2609.24267.
- SWivid/F5-TTS (commit 45868ab),
src/f5_tts/infer/utils_infer.py. - hexgrad/kokoro (commit dfb907a),
kokoro/pipeline.py; hexgrad/misaki (commit fba1236); model card hexgrad/Kokoro-82M (revision f3ff357). - jik876/hifi-gan (commit 4769534), gemelo-ai/vocos (commit eb39abf), NVIDIA/BigVGAN (commit 7d2b454), shivammehta25/Matcha-TTS (commit bd4d90d): configuration files.